Ollama vs oMLX
A side-by-side look at pricing, capabilities, pros, cons, and our editorial scores.
Tagline
Ollama
The de facto runtime for running open-weights LLMs locally, now with a paid cloud tier for bigger models.oMLX
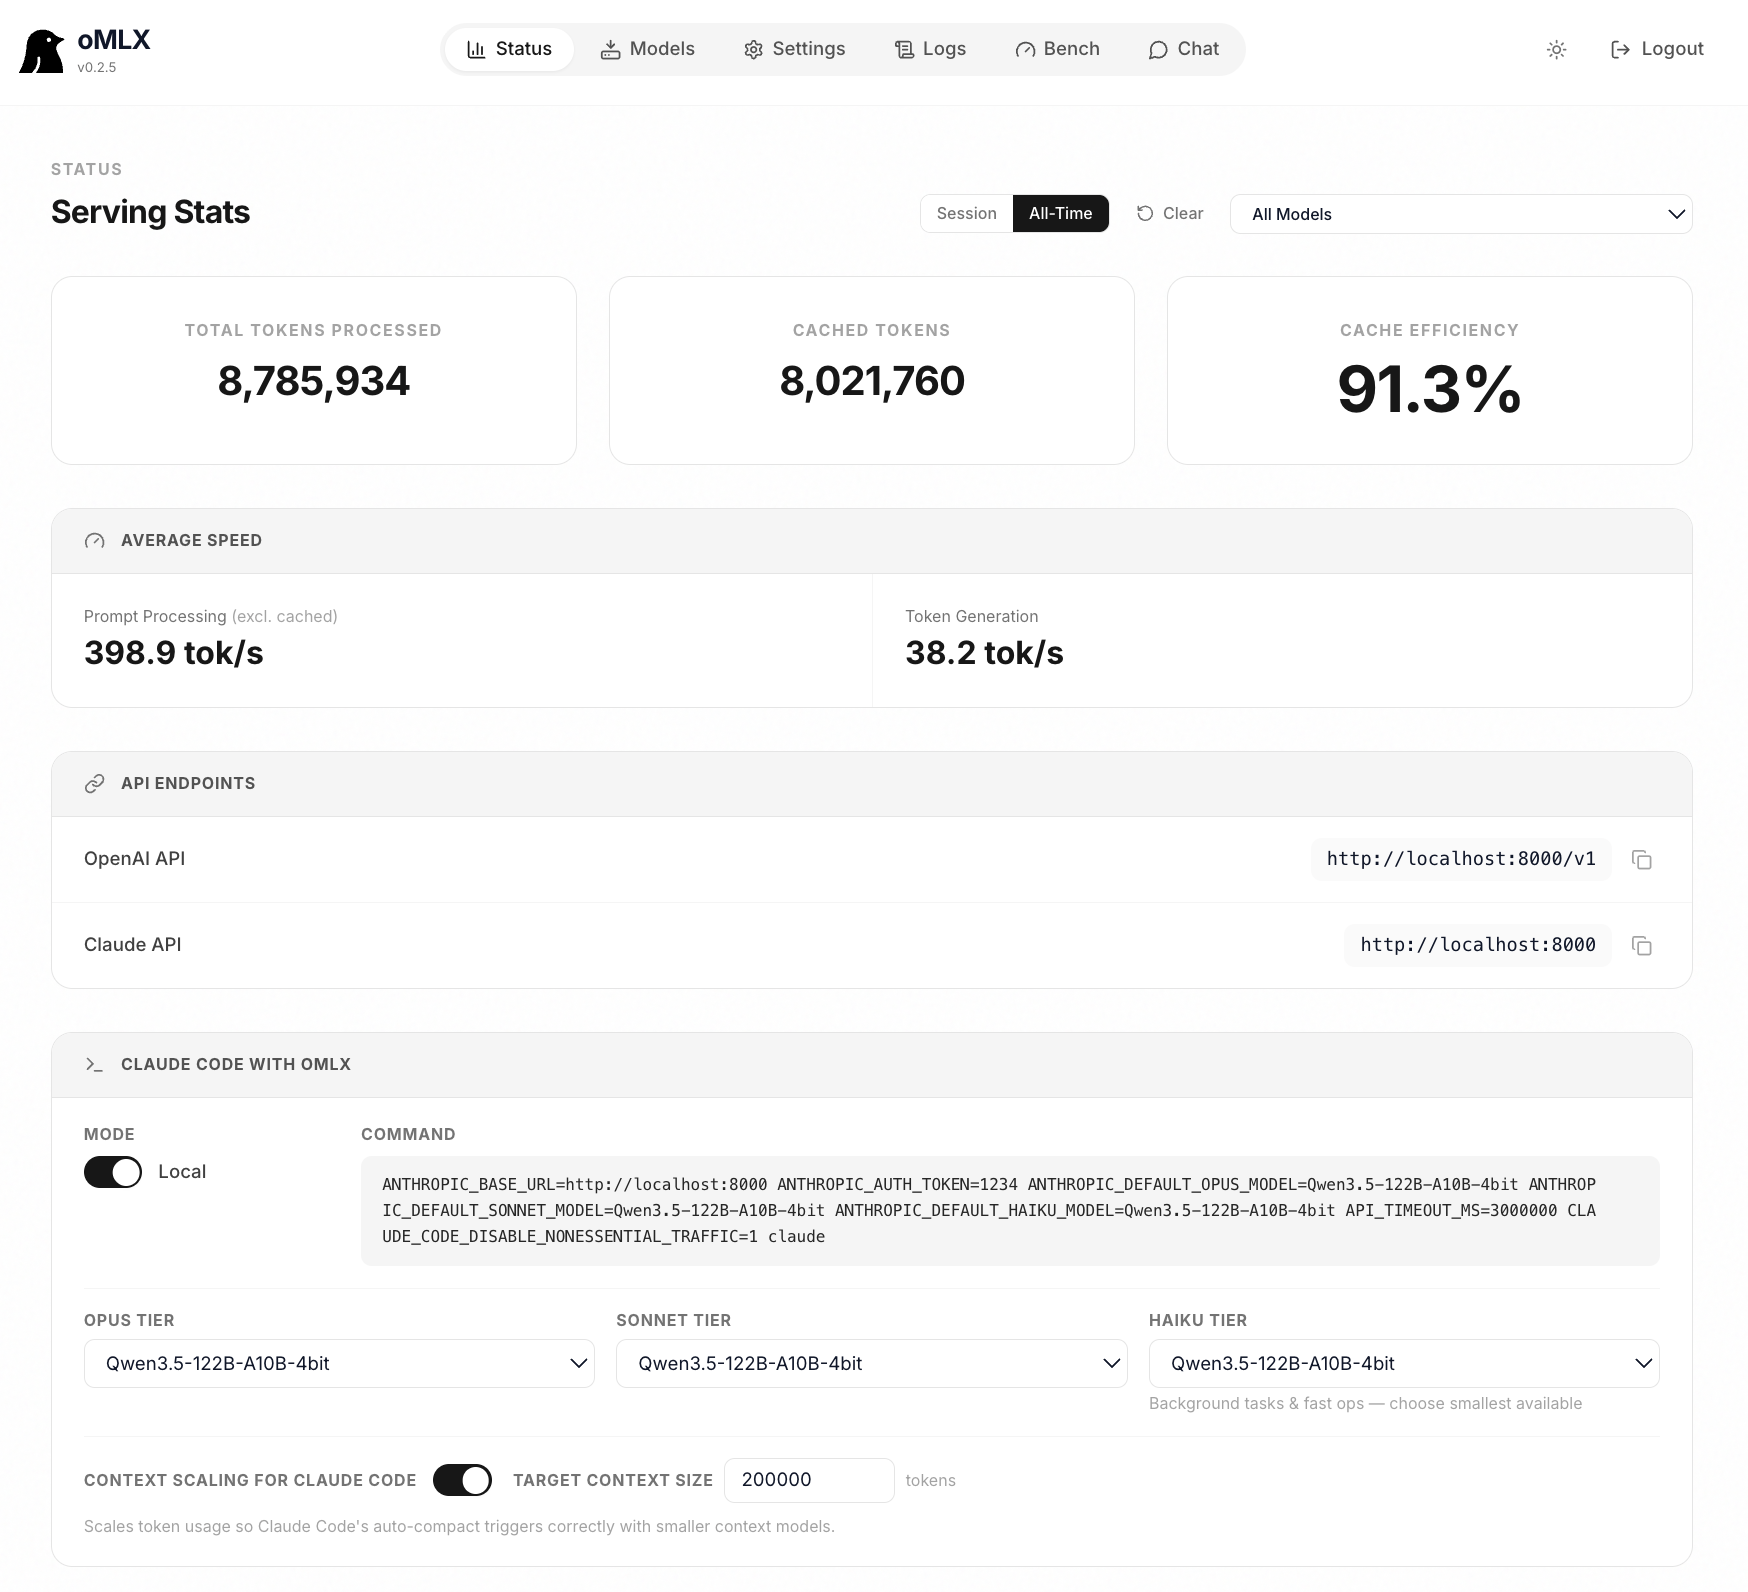
Native macOS LLM inference server built on MLX, with paged SSD KV caching for Apple Silicon agents.Pricing
Ollama
Freemium· Free tier · from $20/mooMLX
Free· Free, Apache 2.0 open sourceLowest paid tier
Ollama
$20 / mo. · Pro
captured 2026-10-28
oMLX
—Free trial
Ollama
YesoMLX
Not listedAPI
Ollama
YesoMLX
YesPlatforms
Ollama
linuxcliapi
oMLX
macoslinuxcliapi
Open source
Ollama
YesoMLX
Yes · Apache-2.0GitHub stars
Ollama
—oMLX
23,586
checked 2026-11-13
Last GitHub push
Ollama
—oMLX
2026-11-12First commit
Ollama
—oMLX
2026-02Hacker News stories
Ollama
69
checked 2026-11-17
oMLX
3
checked 2026-11-17
Earliest Wayback capture
Ollama
—oMLX
2026-03-10
earliest archived capture of the site, not a launch date
Founded
Ollama
2023
Wikidata
oMLX
—Model used
Ollama
Multi-model (Llama, Qwen, Gemma, DeepSeek, Mistral, Phi, etc.)oMLX
Multi-model (Qwen, Llama, Mistral, Gemma, DeepSeek, MiniMax, GLM)Best for
Ollama
Pick Ollama if you want one command to run open-weights LLMs on your own hardware with a clean API that any client can hit.oMLX
Pick oMLX if you run Claude Code, Cursor or other long-context coding agents locally on a beefy Apple Silicon Mac and want sub-5s TTFT.Not for
Ollama
Skip it if you need high-throughput production inference at scale or specifically want frontier closed models like GPT-5 or Claude.oMLX
Skip it if you are on Linux, Windows, NVIDIA, or just want a hosted API - oMLX is Apple Silicon-only and you bring the hardware.Editorial score
Ollama
7.2 / 10oMLX
7.5 / 10Use cases
Ollama
local-llmself-hosted-inferenceprivate-coding-assistantrag-backendoffline-ai
oMLX
local-llm-inferencecoding-agentsapple-siliconopenai-compatible-apimlx
Pros
Ollama
- Easiest path to running open-weights LLMs locally on Mac/Linux/Windows
- OpenAI-compatible API means existing tooling works out of the box
- Huge curated model library with sensible quantization defaults
- Same API for local and cloud lets you scale without rewriting code
- Open source (MIT) with a massive integration ecosystem
oMLX
- Paged SSD KV cache slashes agent TTFT from 30-90s to <5s on long contexts
- Drop-in OpenAI and native Anthropic /v1/messages endpoints for Claude Code, Cursor, OpenClaw
- Continuous batching delivers ~4.14x generation speedup at 8x concurrency
- Native signed/notarized menu-bar app (not Electron) with web dashboard
- Apache 2.0, reuses your existing LM Studio model directory
Cons
Ollama
- Underlying llama.cpp engine is slower than vLLM/SGLang for production serving
- Cloud tier is newer than competitors like Together or Fireworks
- Configuration of GPU offload and context length can be finicky
oMLX
- Apple Silicon and macOS 15+ only - no Linux, Windows or NVIDIA
- Best benchmarks assume an M3 Ultra 512GB few readers actually own
- Young project (VLM support only since v0.2.0) - feature surface still maturing
- No hosted/cloud option; you supply the hardware
Editorial score: rule-based, 0–10, from AI-assisted profile inputs (see /methodology) — not a user rating; “—” means unscored. “Not listed” means we have no record of it, not that it is absent. GitHub figures and prices carry the date they were checked or captured; prices are shown as published, unconverted.
Pick Ollama if
- ✅ Easiest path to running open-weights LLMs locally on Mac/Linux/Windows
- ✅ OpenAI-compatible API means existing tooling works out of the box
- ✅ Huge curated model library with sensible quantization defaults
- ✅ Same API for local and cloud lets you scale without rewriting code
Pick oMLX if
- ✅ Paged SSD KV cache slashes agent TTFT from 30-90s to <5s on long contexts
- ✅ Drop-in OpenAI and native Anthropic /v1/messages endpoints for Claude Code, Cursor, OpenClaw
- ✅ Continuous batching delivers ~4.14x generation speedup at 8x concurrency
- ✅ Native signed/notarized menu-bar app (not Electron) with web dashboard