HoneyHive vs W&B Weave
A side-by-side look at pricing, capabilities, pros, cons, and our editorial scores.
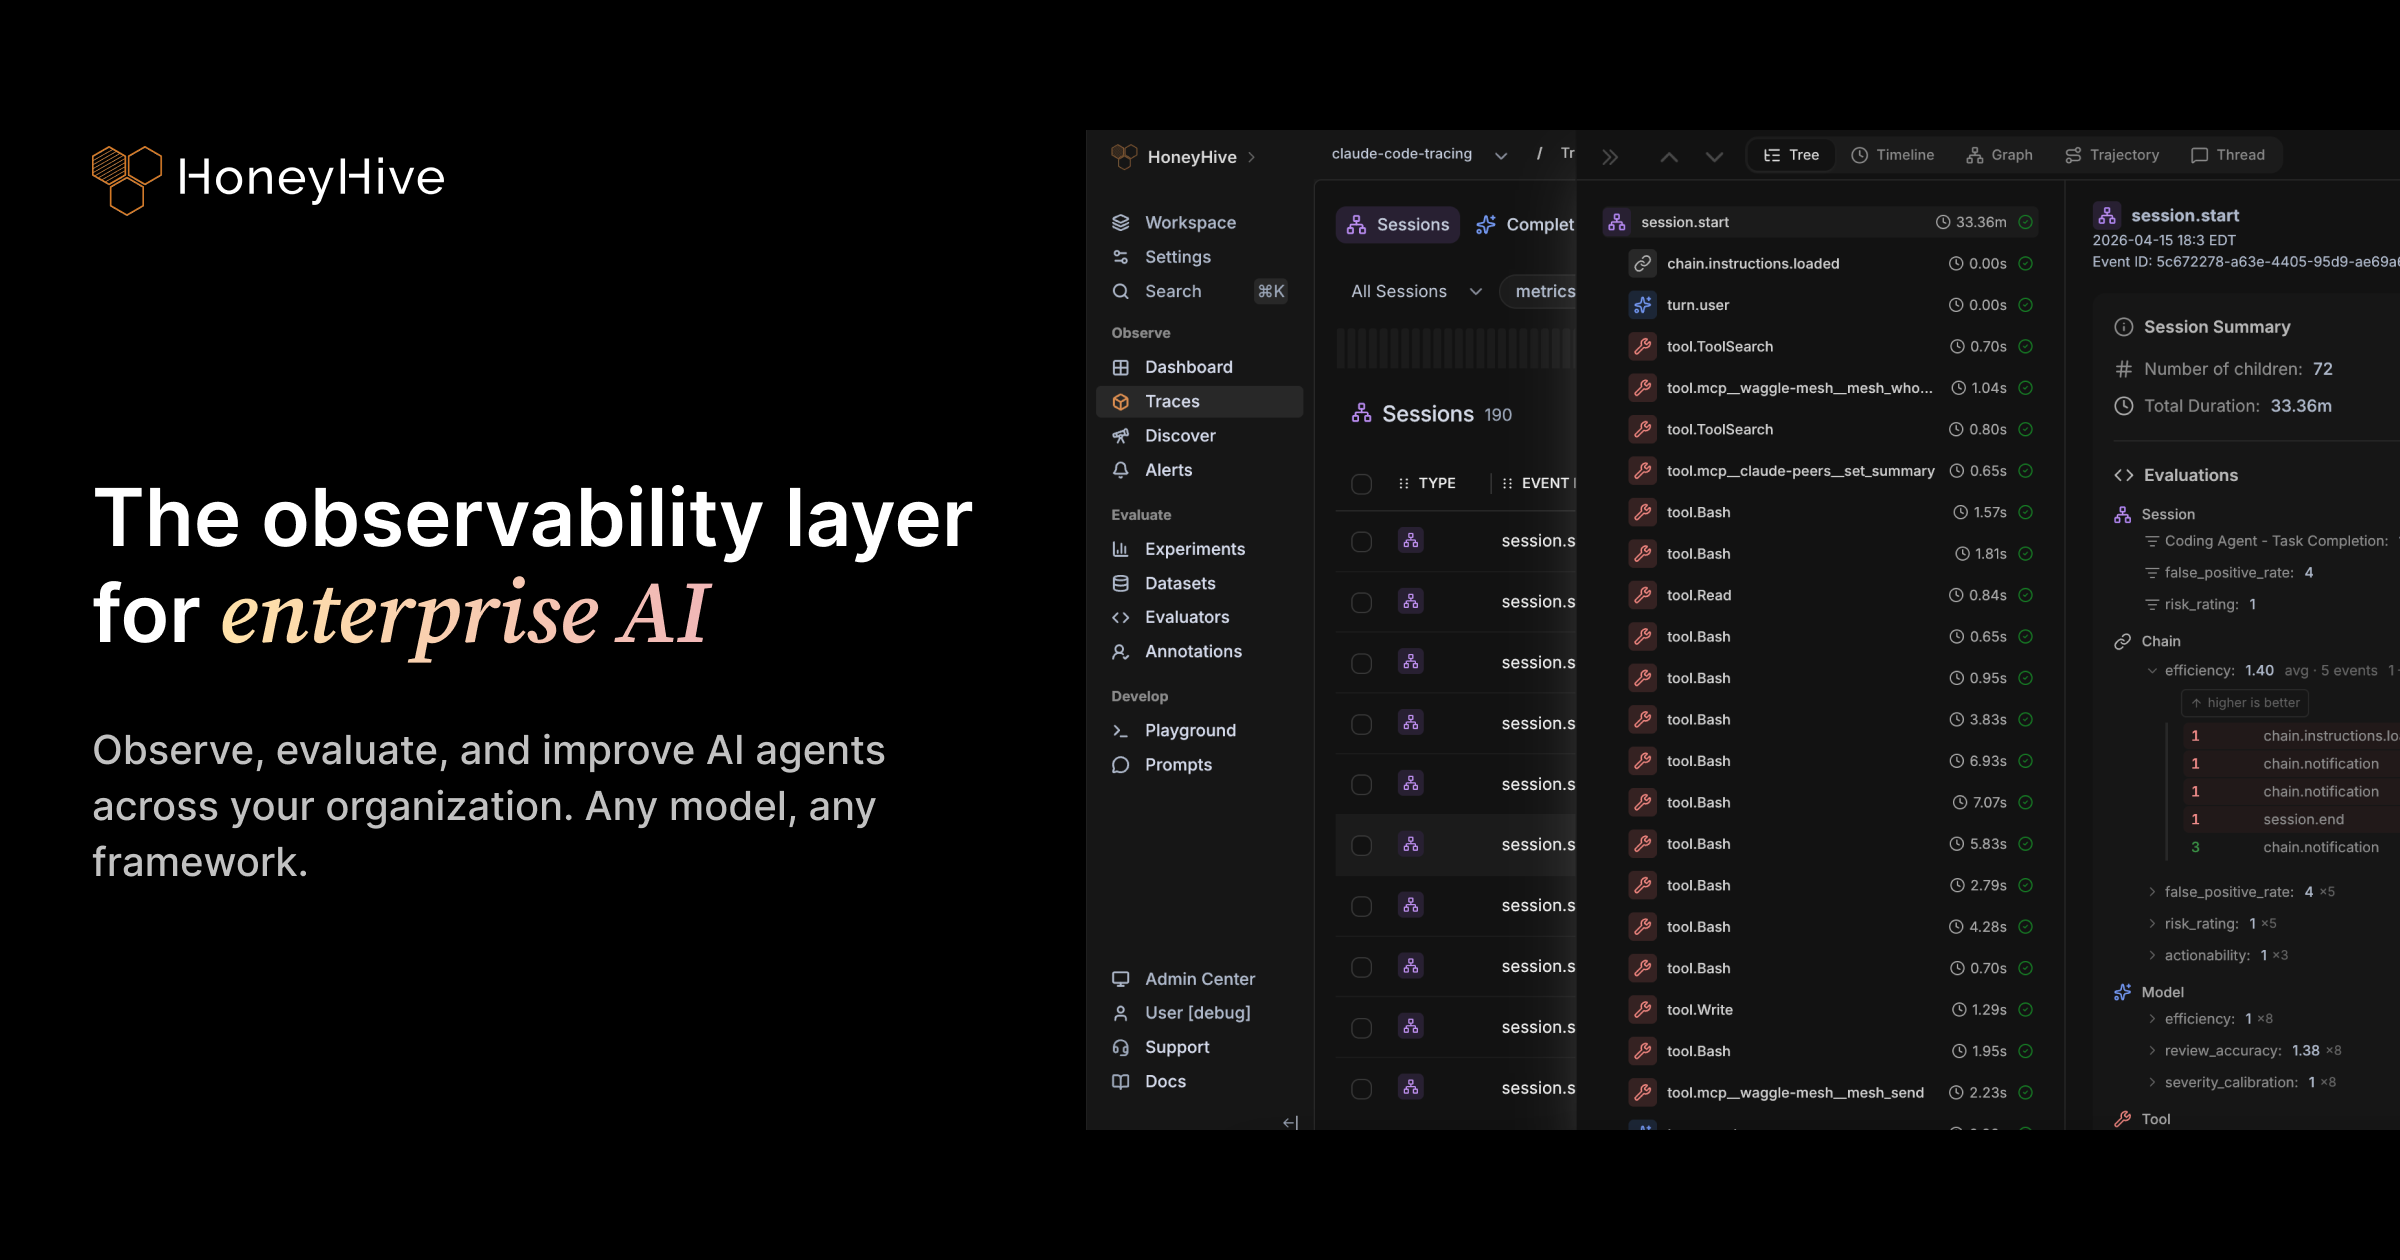

Tagline
HoneyHive
OpenTelemetry-native observability and evaluation platform for LLM agents in production.W&B Weave
Production observability, tracing, and evaluation for LLM and agent systems from the Weights & Biases stack.Pricing
HoneyHive
Freemium· Free tier available; paid/enterprise tiers via salesW&B Weave
Freemium· Free tier available; paid and enterprise plans via W&BFree trial
HoneyHive
YesW&B Weave
YesAPI
HoneyHive
YesW&B Weave
YesPlatforms
HoneyHive
cliapi
W&B Weave
api
Company
HoneyHive
—W&B Weave
Weights & BiasesModel used
HoneyHive
Multi-modelW&B Weave
Multi-modelBest for
HoneyHive
Pick HoneyHive if you're running real LLM agents in production and need tracing, evals, and human review under one OTel-native platform.W&B Weave
Pick W&B Weave if you are shipping multi-turn agents to production and need tracing, evals, and guardrails wired into the same stack as your ML experiments.Not for
HoneyHive
Skip it if you're prototyping a single prompt, want a self-hostable open-source stack, or need transparent published pricing before talking to sales.W&B Weave
Skip it if you just need lightweight prompt logging for a single-call LLM app or want a fully open-source self-hosted observability tool.Editorial score
HoneyHive
8.1 / 10W&B Weave
8.1 / 10Use cases
HoneyHive
agent-observabilityllm-evaluationtracingregression-testinghuman-annotation
W&B Weave
llm-tracingagent-observabilityonline-evaluationguardrailsregression-testingprompt-experimentation
Pros
HoneyHive
- OpenTelemetry-native tracing across 100+ LLMs and frameworks
- Unifies tracing, online eval, experiments, and human annotation
- CI/CD hooks catch regressions before deploy
- MCP server and CLI for IDE-level workflows
- Used by both startups and Fortune 500 teams
W&B Weave
- Agent-native trace model with sessions, turns, tools, and sub-agents
- Built-in scorers for toxicity, bias, PII, and hallucinations
- Playground replays production traces against new prompts/models
- Inherits the maturity of the W&B experiment-tracking platform
- Broad SDK coverage across OpenAI, Anthropic, LangChain, LlamaIndex, DSPy
Cons
HoneyHive
- Pricing not published; enterprise tiers need a sales call
- Closed source SaaS with vendor lock-in on trace format
- Overkill for single-prompt or pre-production projects
W&B Weave
- Pricing not transparent on the LLMOps landing page
- Best value if you are already a W&B customer
- Heavier than minimalist tracing tools for simple single-prompt apps
Editorial score: rule-based, 0–10, from AI-assisted profile inputs (see /methodology) — not a user rating; “—” means unscored. “Not listed” means we have no record of it, not that it is absent. GitHub figures and prices carry the date they were checked or captured; prices are shown as published, unconverted.
Pick HoneyHive if
- ✅ OpenTelemetry-native tracing across 100+ LLMs and frameworks
- ✅ Unifies tracing, online eval, experiments, and human annotation
- ✅ CI/CD hooks catch regressions before deploy
- ✅ MCP server and CLI for IDE-level workflows
Pick W&B Weave if
- ✅ Agent-native trace model with sessions, turns, tools, and sub-agents
- ✅ Built-in scorers for toxicity, bias, PII, and hallucinations
- ✅ Playground replays production traces against new prompts/models
- ✅ Inherits the maturity of the W&B experiment-tracking platform