Forefront vs Replicate
A side-by-side look at pricing, capabilities, pros, cons, and our editorial scores.
Tagline
Forefront
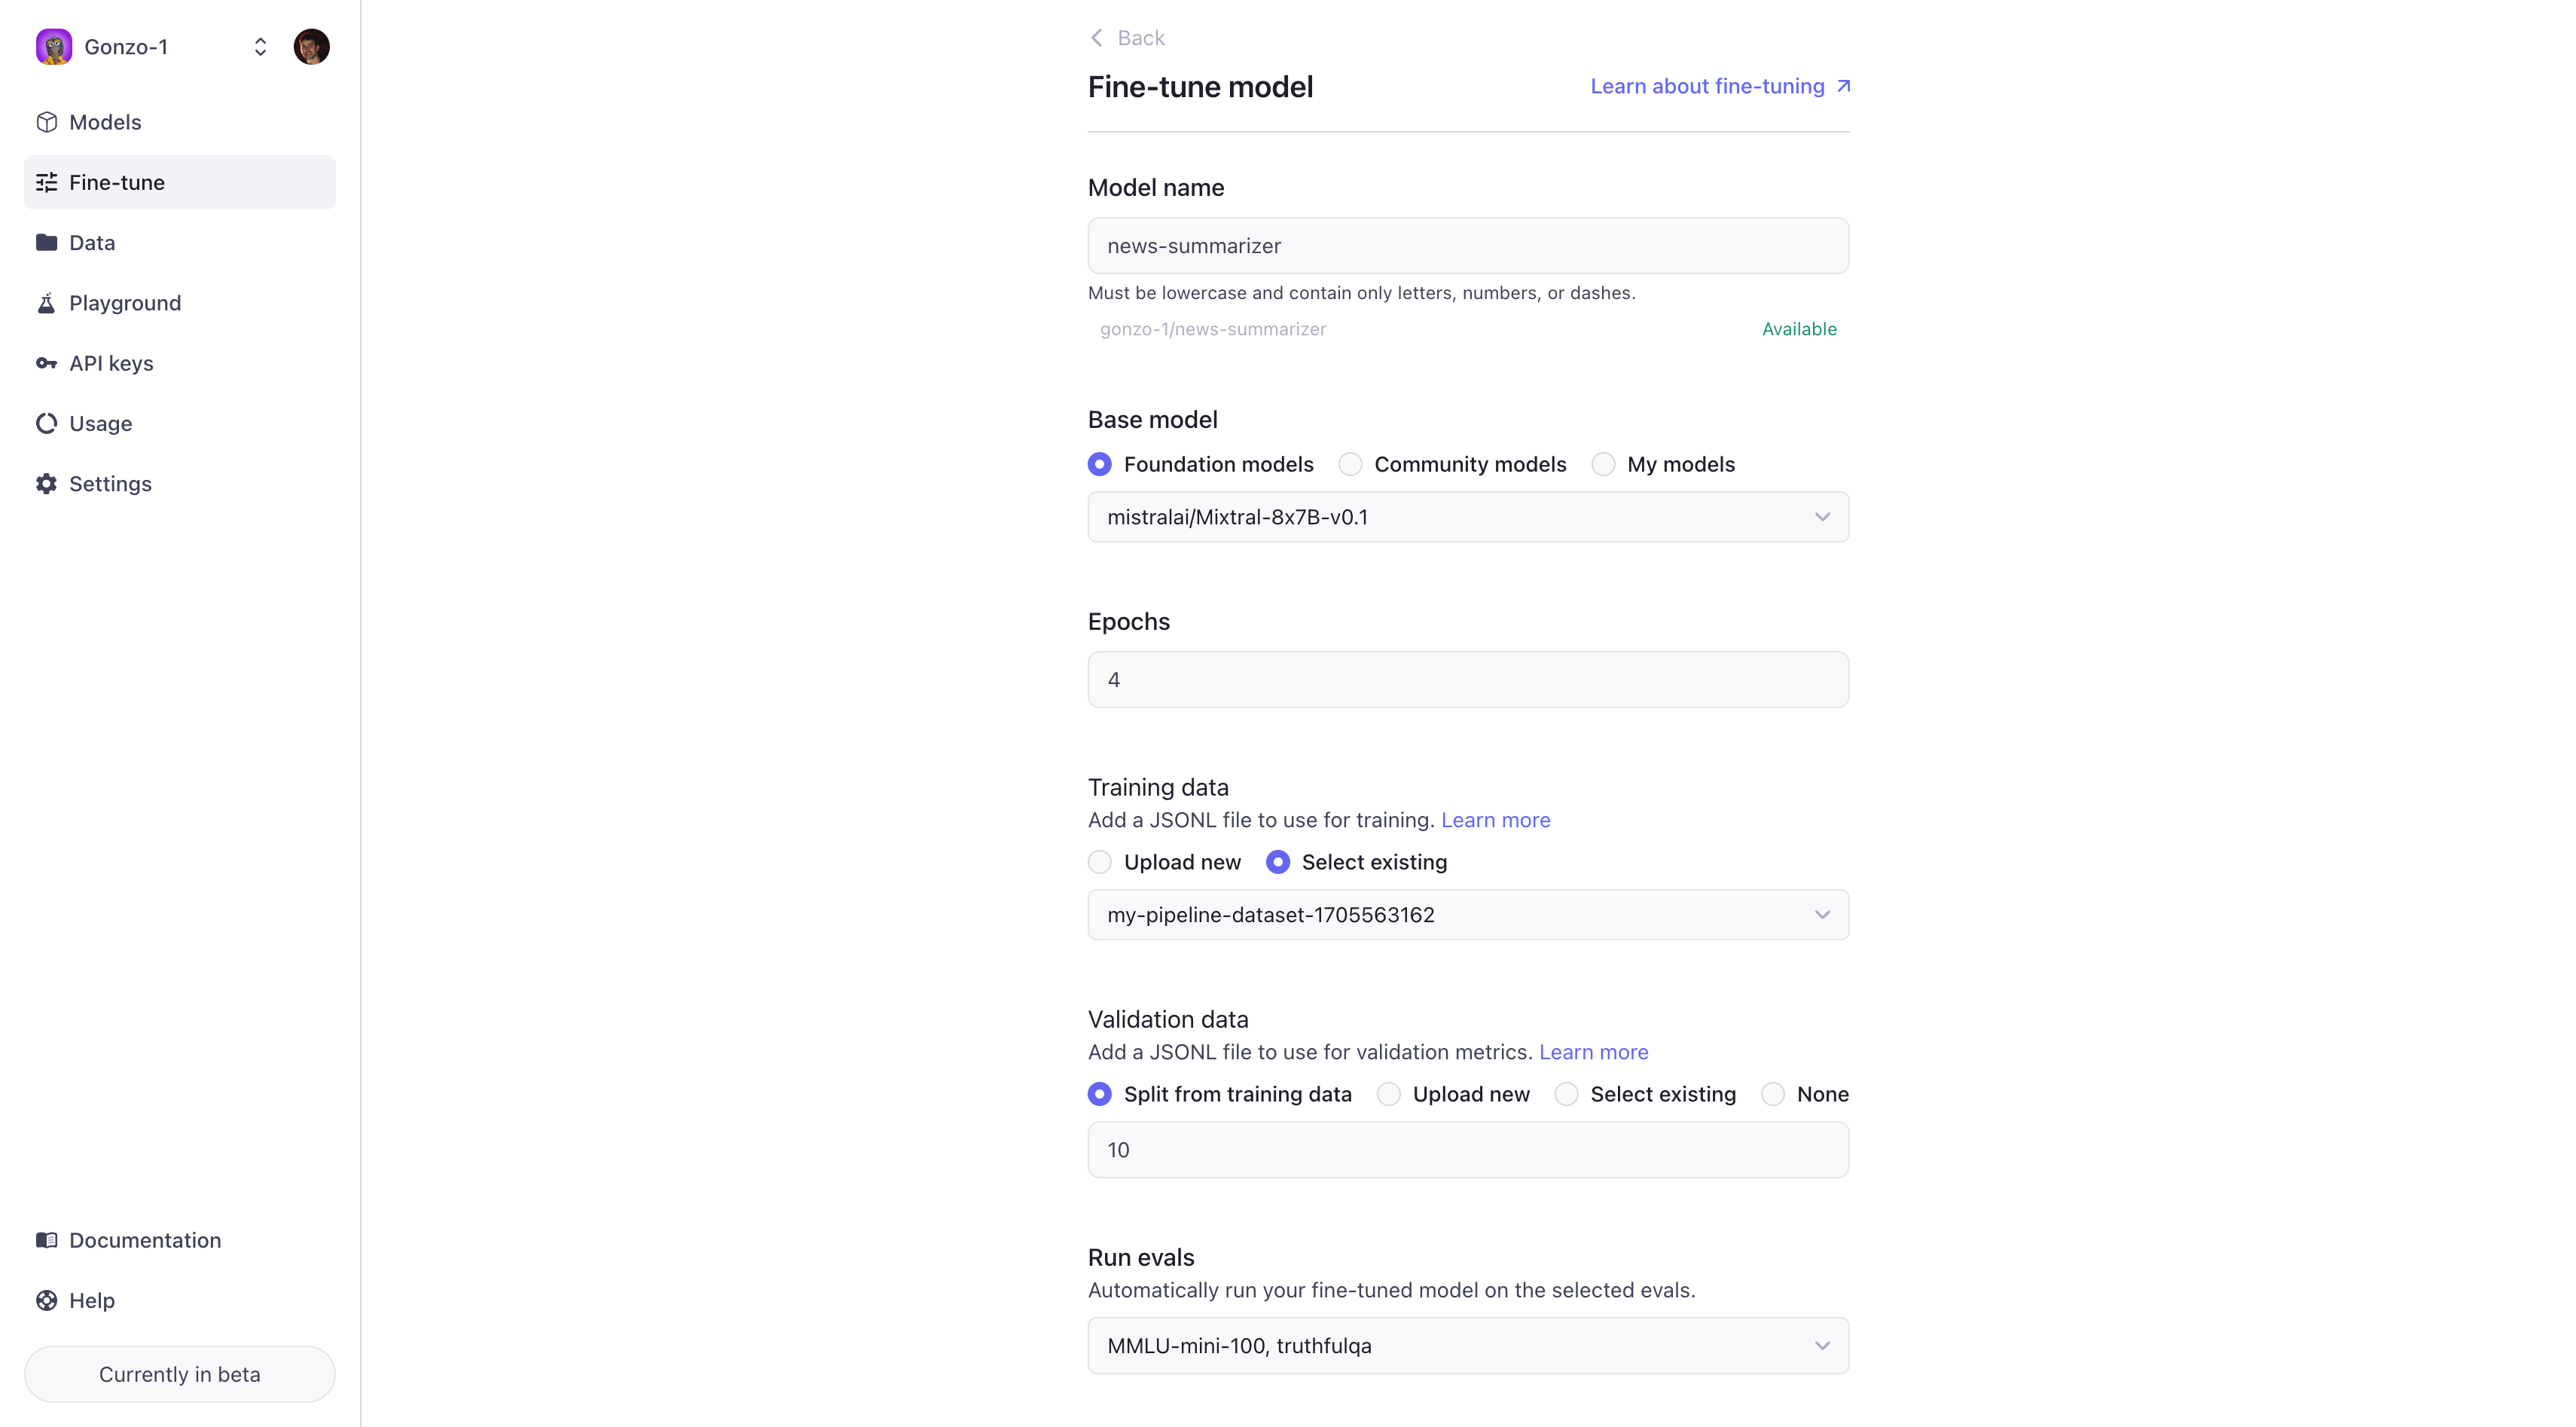
Fine-tune and serve open-source LLMs on your own data without managing GPUs.Replicate
One-API platform for running and fine-tuning open-source models.Pricing
Forefront
PaidReplicate
Paid· Pay-per-second of GPU timeLowest paid tier
Forefront
$99 per month · Team
captured 2026-08-02
Replicate
—API
Forefront
YesReplicate
Not listedPlatforms
Forefront
api
Replicate
api
Open source
Forefront
Not listedReplicate
Not listed · Apache-2.0GitHub stars
Forefront
—Replicate
597
checked 2026-11-13
Last GitHub push
Forefront
—Replicate
2025-11-17First commit
Forefront
—Replicate
2022-11Package downloads (30 d)
Forefront
—Replicate
3,263,078 · npm replicate
checked 2026-11-20
Hacker News stories
Forefront
1
checked 2026-11-11
Replicate
110
checked 2026-11-20
Earliest Wayback capture
Forefront
2022-01-04
earliest archived capture of the site, not a launch date
Replicate
—Company
Forefront
ForefrontReplicate
—Model used
Forefront
Multi-model (Mistral-7B, Mixtral, Phi-2)Replicate
Thousands of community + first-party modelsBest for
Forefront
Pick Forefront if you want to fine-tune a small open-source LLM on proprietary data and serve it via API without standing up your own GPU stack.Replicate
Pick Replicate to experiment across many models or to fine-tune popular open models with minimal setup.Not for
Forefront
Skip it if you need closed frontier models like GPT-4 or Claude, or a polished end-user chatbot rather than a developer fine-tuning workflow.Replicate
Skip it for high-volume production inference where dedicated deployments or self-hosting are cheaper.Editorial score
Forefront
7.0 / 10Replicate
8.5 / 10Use cases
Forefront
fine-tuningopen-source-llmsmodel-hostinginference-apimodel-evaluation
Replicate
model hostingfine-tuningAPI access
Pros
Forefront
- End-to-end workflow: data, training, eval, and inference in one platform
- No GPU provisioning — serverless scaling with per-token pricing
- Built-in benchmarks (MMLU, TruthfulQA, HumanEval) for fine-tune evaluation
- Model export lets you take fine-tuned weights to self-hosted infra
- Privacy posture: no request logging on inference
Replicate
- One API, thousands of models
- Easy fine-tuning of Llama, SD, Flux
- Strong community
- Predictable per-second pricing
Cons
Forefront
- Model catalog is narrower than Together or Replicate
- Developer-only — no end-user chat UI or no-code tooling
- Pricing transparency depends on the specific model tier picked
Replicate
- Per-second pricing can surprise
- Hosted models vary in quality
Editorial score: rule-based, 0–10, from AI-assisted profile inputs (see /methodology) — not a user rating; “—” means unscored. “Not listed” means we have no record of it, not that it is absent. GitHub figures and prices carry the date they were checked or captured; prices are shown as published, unconverted.
Pick Forefront if
- ✅ End-to-end workflow: data, training, eval, and inference in one platform
- ✅ No GPU provisioning — serverless scaling with per-token pricing
- ✅ Built-in benchmarks (MMLU, TruthfulQA, HumanEval) for fine-tune evaluation
- ✅ Model export lets you take fine-tuned weights to self-hosted infra
Pick Replicate if
- ✅ One API, thousands of models
- ✅ Easy fine-tuning of Llama, SD, Flux
- ✅ Strong community
- ✅ Predictable per-second pricing