MixEval
✓ Text source-checked Nov 21, 2026Source-checked against the vendor's site · rebuilt from the vendor's own pagesProfile updated Link checked How we rate
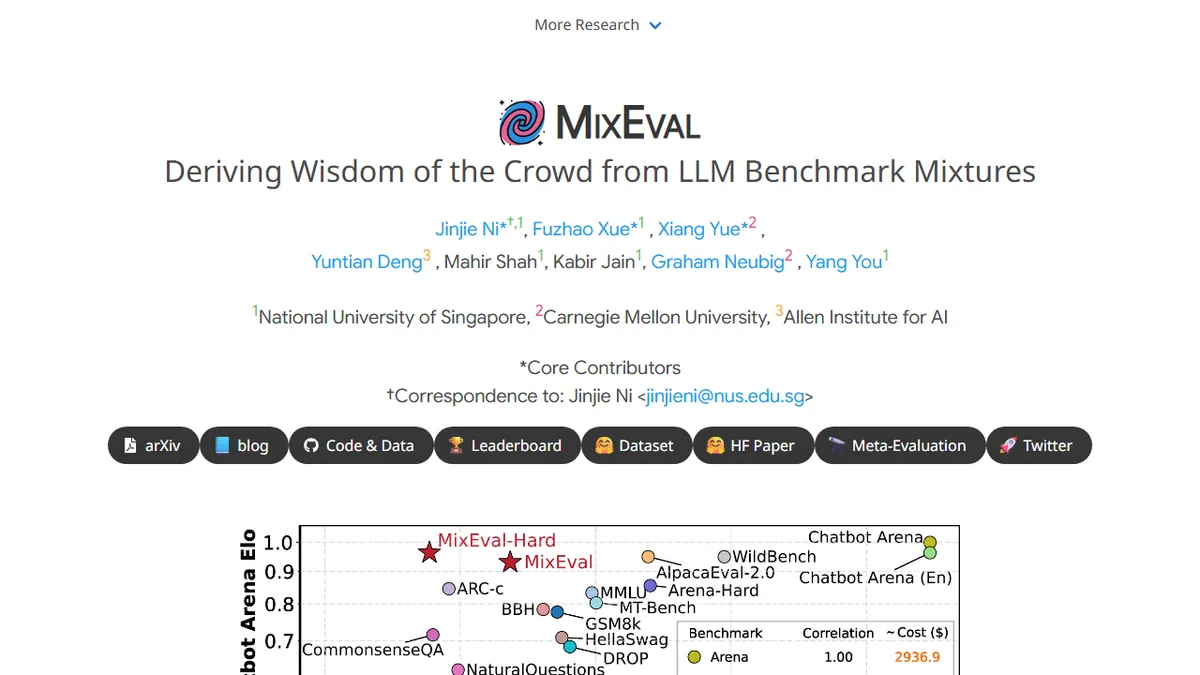
The vendor says that the benchmark bridges real-world user queries and ground-truth evaluation by matching web-mined queries with similar queries from existing datasets. The vendor says that A variant called MixEval-Hard is designed to enhance the benchmark's ability to distinguish strong models.
The project is developed by researchers from the National University of Singapore, Carnegie Mellon University, and the Allen Institute for AI. The work was accepted to NeurIPS 2024.
According to MixEval: The project is developed by researchers from the National University of Singapore, Carnegie Mellon University, and the Allen Institute for AI. Its pages list this strength: Accurate model ranking with a 0.96 correlation to Chatbot Arena.
— The AI Tool Bible editorial team
Pros
- ✅ Accurate model ranking with a 0.96 correlation to Chatbot Arena.
- ✅ The vendor says that fast and cheap execution requiring only 6% the time and cost of MMLU.
- ✅ Dynamic evaluation mechanism to mitigate data contamination.
- ✅ Fair grading process without preference bias due to ground-truth-based nature.
Facts
- Pricing
- free (not source-checked)
- Open source
- Yes (not source-checked)
- GitHub stars
- 253 (checked Nov 13, 2026) (not source-checked)
- Last GitHub push
- Nov 10, 2024 (not source-checked)
- First commit
- Jun 2024 (not source-checked)
- Model used
- GPT-3.5-Turbo-0125, GPT-4o-2024-05-13, Claude 3.5 Sonnet, MixEval, MixEval-Hard (not source-checked)
- Earliest Wayback capture
- 2024-06-05 (earliest archived capture of the site, not a launch date)