MathEval
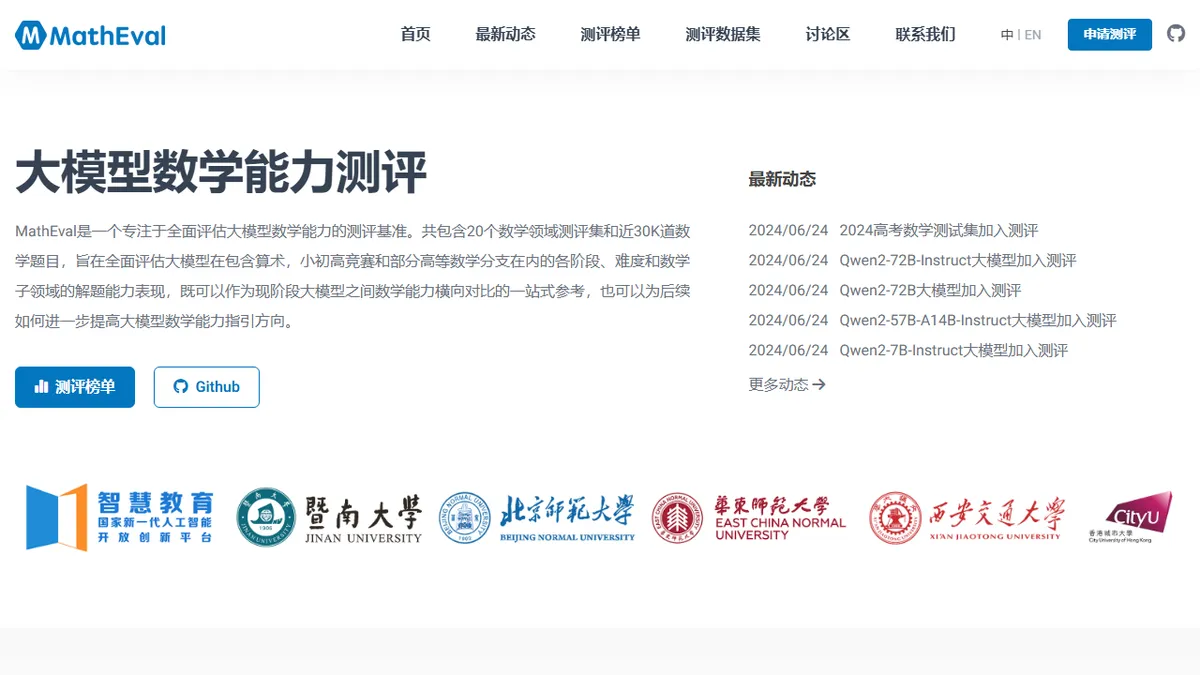
Holistic benchmark suite for evaluating mathematical reasoning in large language models.
In short
MathEval is a free, open-source benchmark suite measuring LLM math reasoning across 22+ datasets. It uses GPT-4 or DeepSeek-LLM-7B for consistent grading to provide defensible scores.
Pick MathEval if you are training or shipping a reasoning model and need a defensible, multi-dataset math score rather than a single cherry-picked GSM8K number.
Skip it if you want a general-purpose LLM eval harness or a hosted API for continuous regression testing inside a product pipeline.
MathEval is a comprehensive benchmark that measures how well large language models actually do math, spanning 22+ datasets and roughly 30,000 problems from elementary arithmetic through college-entrance exams (Gaokao 2023/2024), competition math (AIME, AMC), MATH, GSM8K, MMLU math subsets, and advanced higher-mathematics topics in both English and Chinese. Submissions are run through a standardized pipeline that uses GPT-4 (or a distilled DeepSeek-LLM-7B verifier) for answer extraction and grading, so models are compared against a consistent rubric rather than brittle regex matchers.
It is aimed at LLM researchers, model builders, and infra teams who want a defensible third-party number on math reasoning instead of cherry-picking GSM8K. The pipeline supports HuggingFace checkpoints, API-based models, and custom open-source models, with both zero-shot and few-shot regimes. The project is open source (Python, math-eval org on GitHub) and the leaderboard at matheval.ai is free to read; running an evaluation is done by submitting through the site because end-to-end runs are compute-heavy.
Annually refreshed Gaokao problems are a deliberate hedge against benchmark contamination, which is one of the better reasons to use MathEval over a single static dataset. The trade-off is that there is no turnkey hosted API, evaluations are queued rather than instant, and the project leans academic in tone and cadence.
The most serious public math benchmark we have seen outside of a single lab's leaderboard, and the Gaokao refresh discipline is exactly the right instinct against contamination. Treat it as a research-grade scorecard, not a CI tool, and pair it with your own private holdouts.
— The AI Tool Bible editorial team
Pros
- ✅ Aggregates 22+ math datasets and ~30K problems in one consistent harness
- ✅ GPT-4 grader (or distilled DeepSeek-7B) avoids brittle regex answer matching
- ✅ Annually refreshed Gaokao problems push back on benchmark contamination
- ✅ Supports HF, API, and custom open-source models with zero/few-shot modes
- ✅ Fully open source on GitHub with a published peer-reviewed paper
Cons
- ⚠️ No instant hosted API; runs are queued and compute-heavy
- ⚠️ Leaderboard tooling is academic-grade, not a polished SaaS
- ⚠️ Grader dependency on GPT-4 introduces its own cost and bias surface
- ⚠️ Focus is narrow: math reasoning only, not general capability
Use cases
Frequently asked
- How much does MathEval cost to use?
- MathEval is free and open-source. You can read the leaderboard at matheval.ai for free. Running evaluations requires submitting through the site, as end-to-end runs are compute-heavy and queued rather than instant.
- Which models can I evaluate with MathEval?
- The pipeline supports HuggingFace checkpoints, API-based models, and custom open-source models. It accommodates both zero-shot and few-shot evaluation regimes, allowing researchers to test various model architectures and configurations.
- How does MathEval grade model answers?
- Submissions are processed through a standardized pipeline using GPT-4 or a distilled DeepSeek-LLM-7B verifier for answer extraction and grading. This ensures models are compared against a consistent rubric rather than brittle regex matchers.
- Is MathEval suitable for continuous product testing?
- No, skip it if you need a hosted API for continuous regression testing inside a product pipeline. It is aimed at researchers and model builders seeking defensible third-party numbers, not turnkey hosted APIs for instant results.
- What datasets does MathEval cover?
- It spans 22+ datasets and roughly 30,000 problems, including elementary arithmetic, Gaokao 2023/2024, AIME, AMC, MATH, GSM8K, and MMLU math subsets. It covers advanced higher-mathematics topics in both English and Chinese.
Explore related
Compare with similar tools
All in Evaluation →Braintrust
FeaturedEval, monitor, and improve AI products end-to-end.
LangSmith
LangChain's eval + observability platform.
Weights & Biases
The ML experiment tracker, now with LLM eval features.
Helicone
Open-source LLM observability — one-line proxy install.
Arize AI
Enterprise observability and evaluation platform for LLM agents and generative AI applications.
Giskard
Continuous AI red teaming platform that stress-tests LLM agents for vulnerabilities before they hit production.