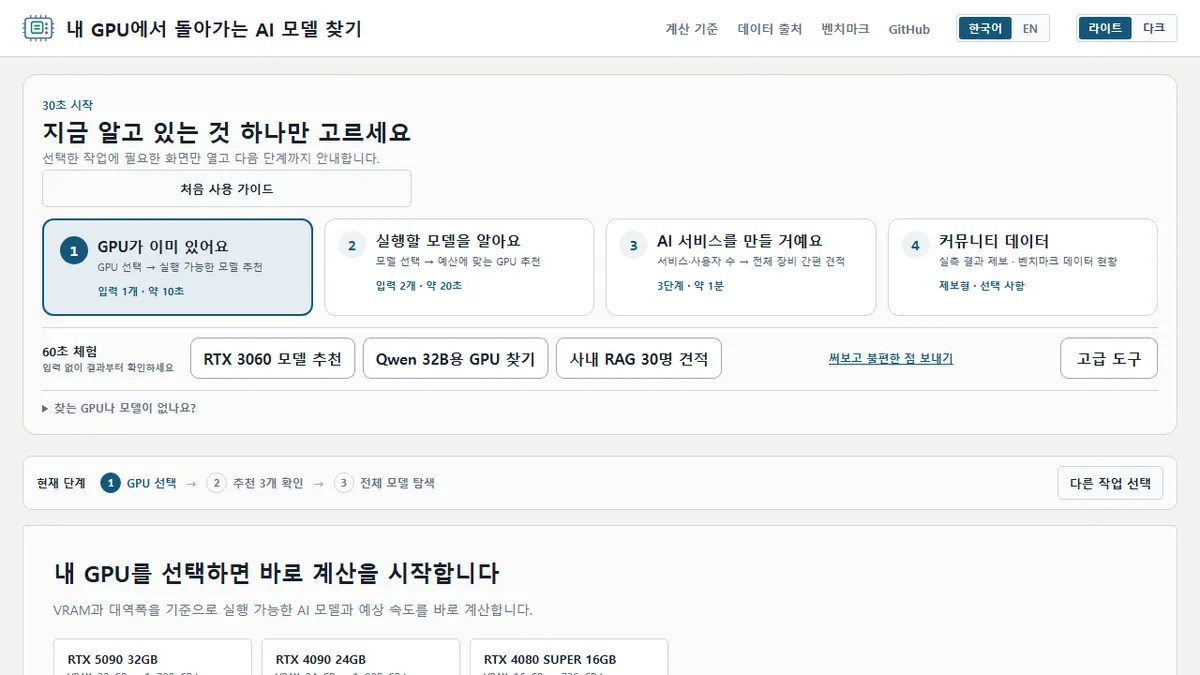
LLM GPU Checker (KO)
Not yet source-checkedMatch LLMs to GPUs and plan multi-model AI stacks by VRAM, bandwidth and precision.
Machine-drafted from the vendor's site · not yet source-checkedProfile updated Link checked How we rate
In short
Free browser tool to match open-source LLMs to GPUs by VRAM and precision. Plan multi-model AI stacks and check hardware fit for self-hosted inference.
Engineers and MLOps teams planning self-hosted LLM deployments on their own GPUs who need a quick VRAM/precision sanity check before procurement or a vLLM/Ollama rollout.
Teams that only consume hosted APIs (OpenAI, Anthropic, Bedrock) and never touch GPU sizing, or anyone needing audited, guaranteed benchmarks for compliance.
LLM GPU Checker (KO) is a free, browser-based capacity-planning tool that helps engineers work out which open-source LLMs will actually run on a given GPU (or set of GPUs), and vice versa. Built by a Korean developer and hosted on GitHub Pages, it offers a bilingual (Korean / English) interface aimed at practitioners standing up self-hosted inference — the audience running vLLM, llama.cpp, Ollama or plain Transformers on their own hardware rather than paying per-token API fees.
The app has four main workflows. GPU-to-Model lets you pick a card (for example an RTX 4090, A100 40GB or H100) and see which models fit at various quantisation levels. Model-to-GPU works the other way: choose a model such as Llama 3.1 70B or Qwen 2.5 and get the minimum viable hardware. A Service Planner takes a workload description (service type, expected concurrent users, context length) and returns an equipment estimate. Finally, an AI Stack Planner distributes LLMs, embedding models, rerankers and OCR/VLM components across multiple GPUs using pipeline, independent-service or sequential execution modes — useful when you are architecting a full RAG or agent stack rather than a single chatbot.
Calculations key off VRAM footprint and memory bandwidth, with adjustable parameters for context length, batch size and precision (FP16, INT8, Q4). Model metadata pulls from the Hugging Face ecosystem, and you can filter the catalog by use case (coding, long-context, vision), license and commercial usability. A community section invites users to submit real-world benchmark numbers so the estimates get grounded over time.
A genuinely useful niche utility — the kind of thing you would otherwise build in a spreadsheet. The stack-planner mode, which lays out LLM + embedder + reranker across multiple cards, is the standout: it maps directly to how real self-hosted RAG deployments are shaped. Treat the numbers as first-pass sizing, not a benchmark.
— The AI Tool Bible editorial team
Pros
- ✅ Bilingual Korean/English UI, rare in the self-hosting tools space
- ✅ Handles multi-GPU stack planning, not just single-model sizing
- ✅ Precision-aware (FP16 / Q8 / Q4) so quantised deployments get realistic estimates
- ✅ Covers the full RAG stack: LLM, embedding, reranker, OCR/VLM allocation
- ✅ Free, no login, runs entirely in the browser
- ✅ Includes commercial-license filtering for enterprise procurement
- ✅ Community benchmark submissions ground the theoretical numbers
Cons
- ⚠️ Estimates are approximations — real throughput depends on driver, kernel and framework specifics not captured here
- ⚠️ GitHub Pages hosting means no SLA, no accounts and no saved projects
- ⚠️ Model catalog is limited to what the maintainer curates from Hugging Face
- ⚠️ No cost modelling versus cloud API alternatives
- ⚠️ UI is functional but visually spartan compared to commercial capacity planners
Facts
- Open source
- Yes
- Model used
- Catalog covers open models on Hugging Face (Llama, Qwen, Mistral, Gemma, etc.)
- Hacker News
- 1 story · top 5 points · last Aug 24, 2026 · checked Nov 15, 2026
Where this tool sits
Use cases
Frequently asked
- Is LLM GPU Checker (KO) free to use?
- Yes, it is a free, open web tool hosted on GitHub Pages. It is designed for engineers planning self-hosted deployments who need a quick VRAM and precision sanity check before procurement.
- Which models and GPUs does the tool support?
- The catalog covers open models on Hugging Face, including Llama, Qwen, Mistral, and Gemma. You can select various GPUs like RTX 4090, A100, or H100 to see which models fit at different quantization levels.
- Can I plan multi-GPU setups for RAG or agent stacks?
- Yes, the AI Stack Planner distributes LLMs, embedding models, rerankers, and OCR/VLM components across multiple GPUs. It supports pipeline, independent-service, or sequential execution modes for full stack architecture.
- What parameters can I adjust for capacity calculations?
- Calculations key off VRAM footprint and memory bandwidth. You can adjust parameters for context length, batch size, and precision (FP16, INT8, Q4) to get accurate hardware estimates for your specific workload.
- Who should skip using this tool?
- Teams that only consume hosted APIs like OpenAI or Anthropic and never touch GPU sizing should skip it. It is also not for anyone needing audited, guaranteed benchmarks for compliance purposes.